Georgia Liu
Measuring Similarity in Causal Graphs: A Framework for Semantic and Structural Analysis
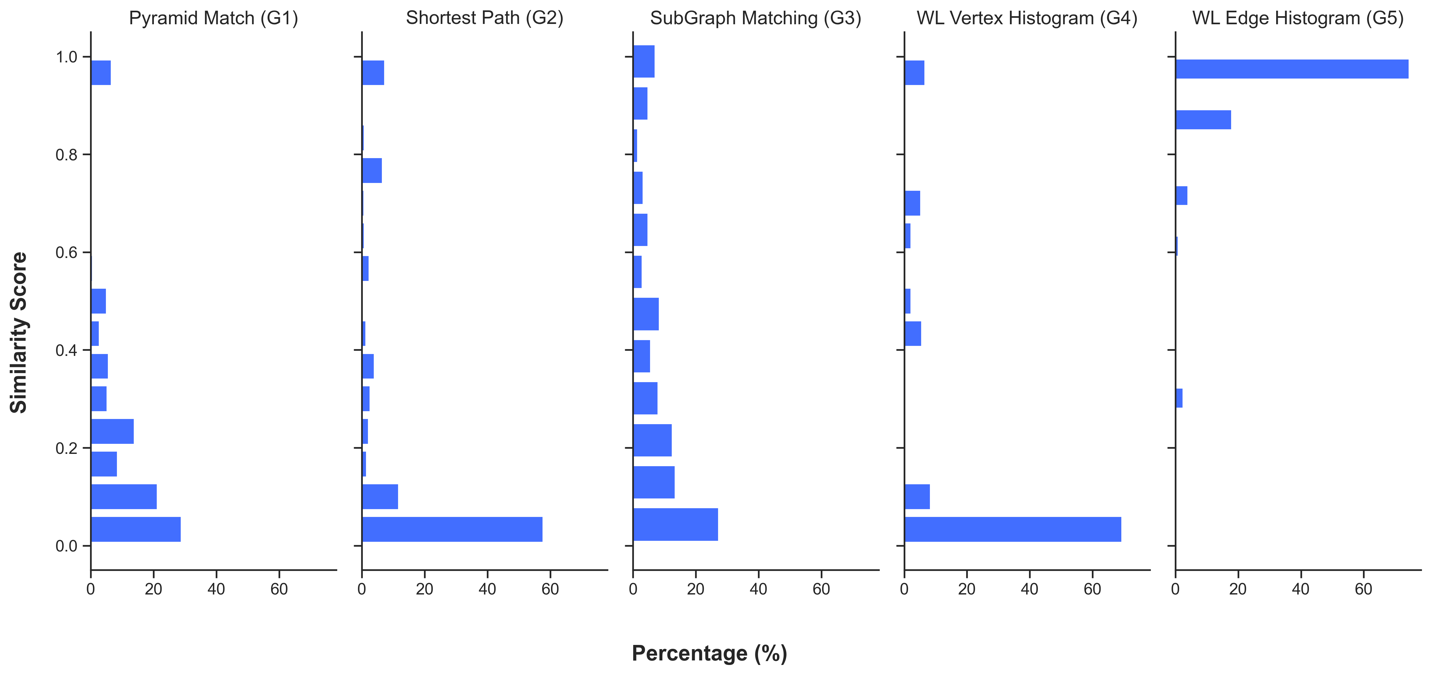
I built a benchmark for evaluating LLM-generated causal graphs: I reviewed 40+ semantic and structural similarity metrics (NLP and graph kernel methods), selected 9, and validated them on 2,000 LLM-generated graphs. The benchmark compares causal graphs on both structural differences and the meaning of variable names. Using AI-generated synthetic data, we simulated how different people might map the same system. Our findings highlight key trade-offs between structural and semantic metrics, paving the way for better tools to interpret both human- and AI-generated models.